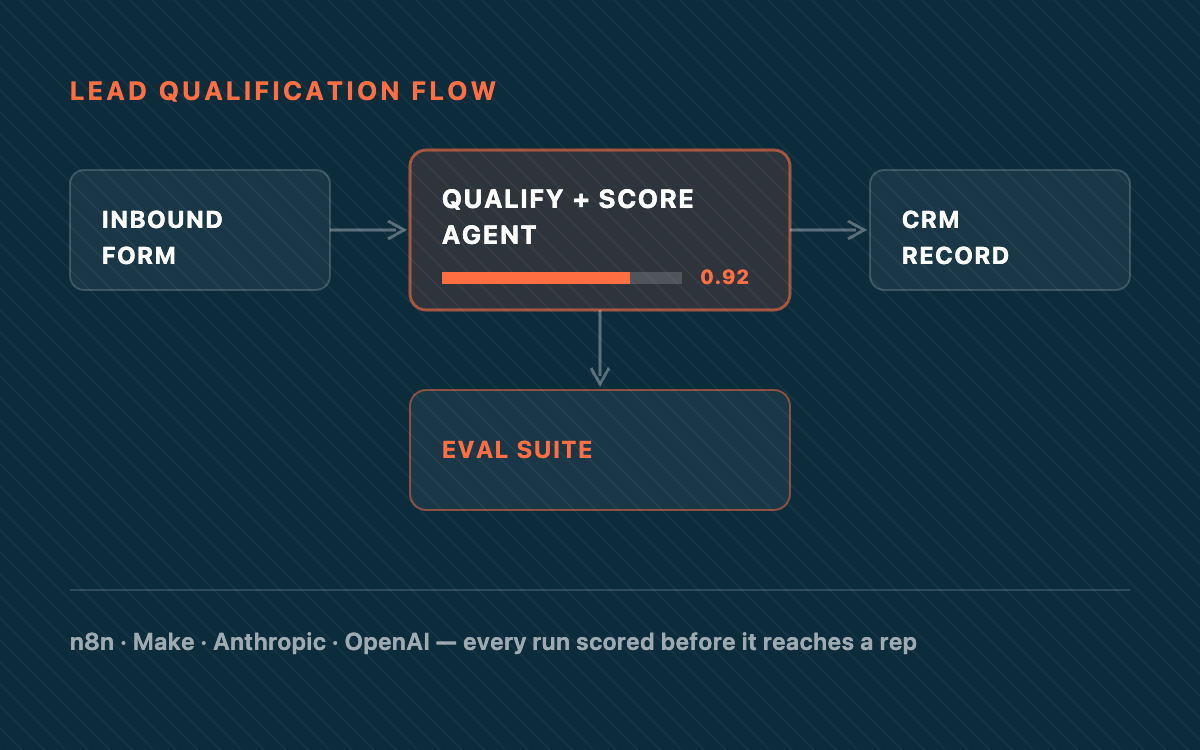
Designed and deployed an AI-powered lead qualification agent for a real estate developer receiving high-volume inbound interest across master-planned communities in Calgary and Edmonton.
The Challenge
Sales teams were manually reviewing every inbound lead, spending hours on unqualified prospects while high-intent buyers waited. No consistent scoring criteria existed across communities.
Constraints
- Must integrate with existing CRM without disrupting active sales workflows
- Qualification logic must be auditable and explainable to stakeholders
- System must handle variable lead volume across multiple community launches
The Approach
Built an agentic workflow on n8n and Make that calls Anthropic and OpenAI APIs to qualify, score, and enrich inbound leads before pushing them to the CRM. Designed a structured eval framework with test cases, expected-vs-actual comparisons, and documented failure modes — proving the system works before trusting it with real leads.
Key Decisions
Use a structured eval framework before production deployment
AI systems need measurable proof of accuracy. The eval documents test cases, expected vs. actual outputs, and failure modes — so stakeholders trust the system and edge cases are caught early.
- Manual spot-checking of outputs
- A/B test against human reviewers
Dual-model architecture (Anthropic + OpenAI)
Different models excel at different qualification subtasks. Using both allows routing by task type and provides fallback redundancy.
Tech Stack
Result & Impact
Sales teams now work pre-qualified, scored leads with enriched context. The eval framework provides ongoing confidence in system accuracy and catches drift before it affects pipeline quality.
Learnings
- The eval is the product — without documented test cases and failure modes, an AI agent is a demo, not a system
- Stakeholder trust comes from showing the methodology, not just the results
Full case study in progress.